
Technical Overview of the Anthropic AI Espionage Attack for SOC Teams
The Anthropic AI espionage case proves attackers trust autonomous agents. To counter machine-speed threats, SOCs must adopt and trust AI to handle 90% of the defense workload.
The first publicly documented, large-scale AI-orchestrated cyber-espionage campaign is now out in the open. Anthropic disclosed that threat actors (assessed with high confidence as a Chinese state-sponsored group) misused Claude Code to run the bulk of an intrusion targeting roughly 30 global organizations across tech, finance, chemical manufacturing, and government.
This attack should serve as a wake-up call, not because of what it is, but because of what it enables. The attackers used written scripts and known vulnerabilities, with AI primarily acting as an orchestration and reconnaissance layer; a "script kiddy" rather than a fully autonomous hacker. This is just the start.
In the near future, the capabilities demonstrated here will rapidly accelerate. We can expect to see actual malware that writes itself, finds and exploits vulnerabilities on the fly, and evades defenses in smart, adaptive ways. This shift means that the assumptions guiding SOC teams are changing.
What Actually Happened: The Technical Anatomy
The most critical takeaway from this campaign is not the technology used, but the level of trust the attackers placed in the AI. By trusting the model to carry out complex, multi-stage operations without human intervention, they unlocked significant, scalable capabilities far beyond human tempo.
1. Attackers “Jailbroke” the Model
Claude’s safeguards weren’t broken with a single jailbreak prompt. The actors decomposed malicious tasks into small, plausible “red-team testing” requests. The model believed it was legitimately supporting a pentest workflow. This matters because it shows that attackers don’t need to “break” an LLM. They just need to redirect its context and trust it to complete the mission.
2. AI Performed the Operational Heavy Lifting
The attackers trusted Claude Code to execute the campaign in an agentic chain autonomously:
- Scanning for exposed surfaces
- Enumerating systems and sensitive databases
- Writing and iterating exploit code
- Harvesting credentials and moving laterally
- Packaging and exfiltrating data
Humans stepped in only at a few critical junctures, mainly to validate targets, approve next steps, or correct the agent when it hallucinated. The bulk of the execution was delegated, demonstrating the attackers’ trust in the AI’s consistency and thoroughness.
3. Scale and Tempo Were Beyond Human Patterns
The agent fired thousands of requests. Traditional SOC playbooks and anomaly models assume slower human-driven actions, distinct operator fingerprints, and pauses due to errors or tool switching. Agentic AI has none of those constraints. The campaign demonstrated a tempo and scale that is only possible when the human operator takes a massive step back and trusts the machine to work at machine speed.
4. Anthropic Detected It and Shut It Down
Anthropic’s logs flagged abnormal usage patterns, disabled accounts, alerted impacted organizations, worked with governments, and released a technical breakdown of how the AI was misused.

The Defender’s Mandate: Adopt and Trust Defensive AI
Attackers have already made the mental pivot, treating AI as a trusted, high-velocity force multiplier for offense. Defenders must meet this shift head-on. If you don't adopt defensive AI, you are falling behind adversaries who already have.
Defenders must further adopt AI and trust it to carry out workflows where it has a decisive advantage: consistency, thoroughness, speed, and scale.
1. Attack Velocity Requires Machine Speed Defense
When an agent can operate at 50–200x human tempo, your detection assumptions rot fast. SOC teams need to treat AI-driven intrusion patterns as high-frequency anomalies, not human-like sequences.
2. Trust AI for High-Volume, Deterministic Workflows
Existing detection pipelines tuned on human patterns will miss sub-second sequential operations, machine-generated payload variants, and coordinated micro-actions. Agentic workloads look more like automation platforms than human operators.
Defenders need to accept the uncomfortable reality that manual triage for these types of intrusions is pointless. You need systems that can sift through massive alert loads, isolate and contain suspicious agentic behavior as it unfolds.
This is where the defense’s trust must be applied. Only the genuinely complex cases should ever reach a human. The SOC must delegate and trust AI to handle triage, investigation, and response with machine-like consistency.
3. “AI vs. AI” is No Longer Theoretical
Attackers have already made the mental pivot: AI is a force multiplier for offense today. Defenders need to accept the same reality. And Anthropic said this out loud in their conclusion:
“We advise security teams to experiment with applying AI for defense in areas like SOC automation, threat detection, vulnerability assessment, and incident response.”
That’s the part most vendors avoid saying publicly, because it commits them to a position. If you don’t adopt defensive AI, you’re falling behind adversaries who already have.
Where SOC Teams Should Act Now
Build Detection for Agentic Behaviors
Start by strengthening detection around behaviors that simply don’t look human. Agentic intrusions move at a pace and rhythm that operators can’t match: rapid-fire request chains, automated tool-hopping, endless exploit-generation loops, and bursty enumeration that sweeps entire environments in seconds. Even lateral movement takes on a mechanical cadence with no hesitation.
These patterns stand out once you train your systems to look for them, but they won’t surface through traditional detection tuned for human adversaries.
Make AI a Core Strategy, Not an Experiment
Start thinking of adopting AI to fight specific offensive AI use cases, whilst keeping your human SOC on its routine.
Defenders have to meet this shift head-on and start using AI against the very tactics it enables. The volume and velocity of these intrusions make manual triage pointless.
You need systems that can sift through massive alert loads, isolate and contain suspicious agentic behavior as it unfolds, generate and evaluate countermeasures on the fly, and digest massive log streams without slowing down. Only the genuinely complex cases should ever reach a human. This isn’t aspirational thinking; attackers have already proven the model works.
Key Takeaway
For SOC teams, the takeaway is that defense has to evolve at the same pace as offense. That means treating AI as a core operational capability inside the SOC, not an experiment or a novelty.
The Defender’s AI Mandate: Trust AI to handle tasks where it excels: consistency, thoroughness, and scale.
The Defender’s AI Goal: Delegate volume and noise to defensive AI agents, freeing human analysts to focus only on genuinely complex, high-confidence threats that require strategic human judgment.
Legion Security will continue publishing analysis, defensive patterns, and applied research in this space. If you want a deeper dive into detection signatures or how to operationalize defensive AI safely, just say the word.
Security investigations rarely start with all the context needed to reach the right decision, and we see plenty of examples of this in real environments. Let’s look at an anonymized but recent example. Every quarter, a publicly traded enterprise’s finance team uploads the company's still-unreleased earnings package which consists of revenue, forecasts, and results that won't go public until earnings day to a restricted SharePoint site for executive review. The package contains sensitive financial information so the upload triggers a DLP alert for review. Pretty standard stuff.
That alert triggered an analyst investigation where the incident response team confirmed the uploader was indeed a part of the reporting team, the destination was the approved site, and access was limited to only the small group of executives who were supposed to see it. Nothing dangerous, so it was safely closed as benign. This single investigation established the conditions that made the activity safe: who was expected to upload the file, where it was supposed to go, and who was supposed to have access.
But the lingering question is… what should be carried forward and/or codified from that investigation? This question is one that we’re obsessed with answering and helping our customers address.
With Legion, instead of carrying forward a single verdict from a single investigation, enterprises can uniquely capture the conditions that each investigation establishes together with the underlying and complementing evidence behind them. On a continuous basis. This holistic view matters, particularly in today’s world, because the same activity type doesn't always mean the same thing, and this is a constantly moving target as environments change. Using our ‘finance team uploading earnings files into SharePoint’ example, one of the conditions that was met, who had access to the folder, can change very quickly. So perhaps the next time, the package is the same, the site is the same, the timing is the same, but the folder may have been shared with an external account or a new unverified user.
The challenge isn't collecting more data. Most enterprises already have plenty of it, scattered across identity providers, endpoints, SaaS apps, and past investigations. The challenge is turning that raw data into knowledge that's reliable enough, and accessible enough, for agents to actually reason over: preserving what made something true, connecting it to the organizational context around it, and continuously testing whether it still holds as the organization changes.
Knowledge needs conditions, not conclusions
That's why Legion represents organizational knowledge and context as a continuously evolving model that connects identities, teams, systems, data, access, behaviors, and the evidence establishing how they all relate to one another.
Legion’s knowledge isn't built from investigations alone. Legion brings information from across the environment, including identities, access, systems, infrastructure, and the relationships between them, into the same layer. Past investigations add another important source, giving Legion an accumulated history from day one: what analysts already checked, what they found, and the evidence that supported those decisions.
Raw data on its own doesn't tell an agent much. An identity, a login, a file upload, a network connection, in isolation, are just data points. What makes this usable is the relationship it has to everything around it. That's what turns data into knowledge an agent can actually act on: not just what happened, but who was involved, what it touched, what normally follows it, and what it means if it doesn't.
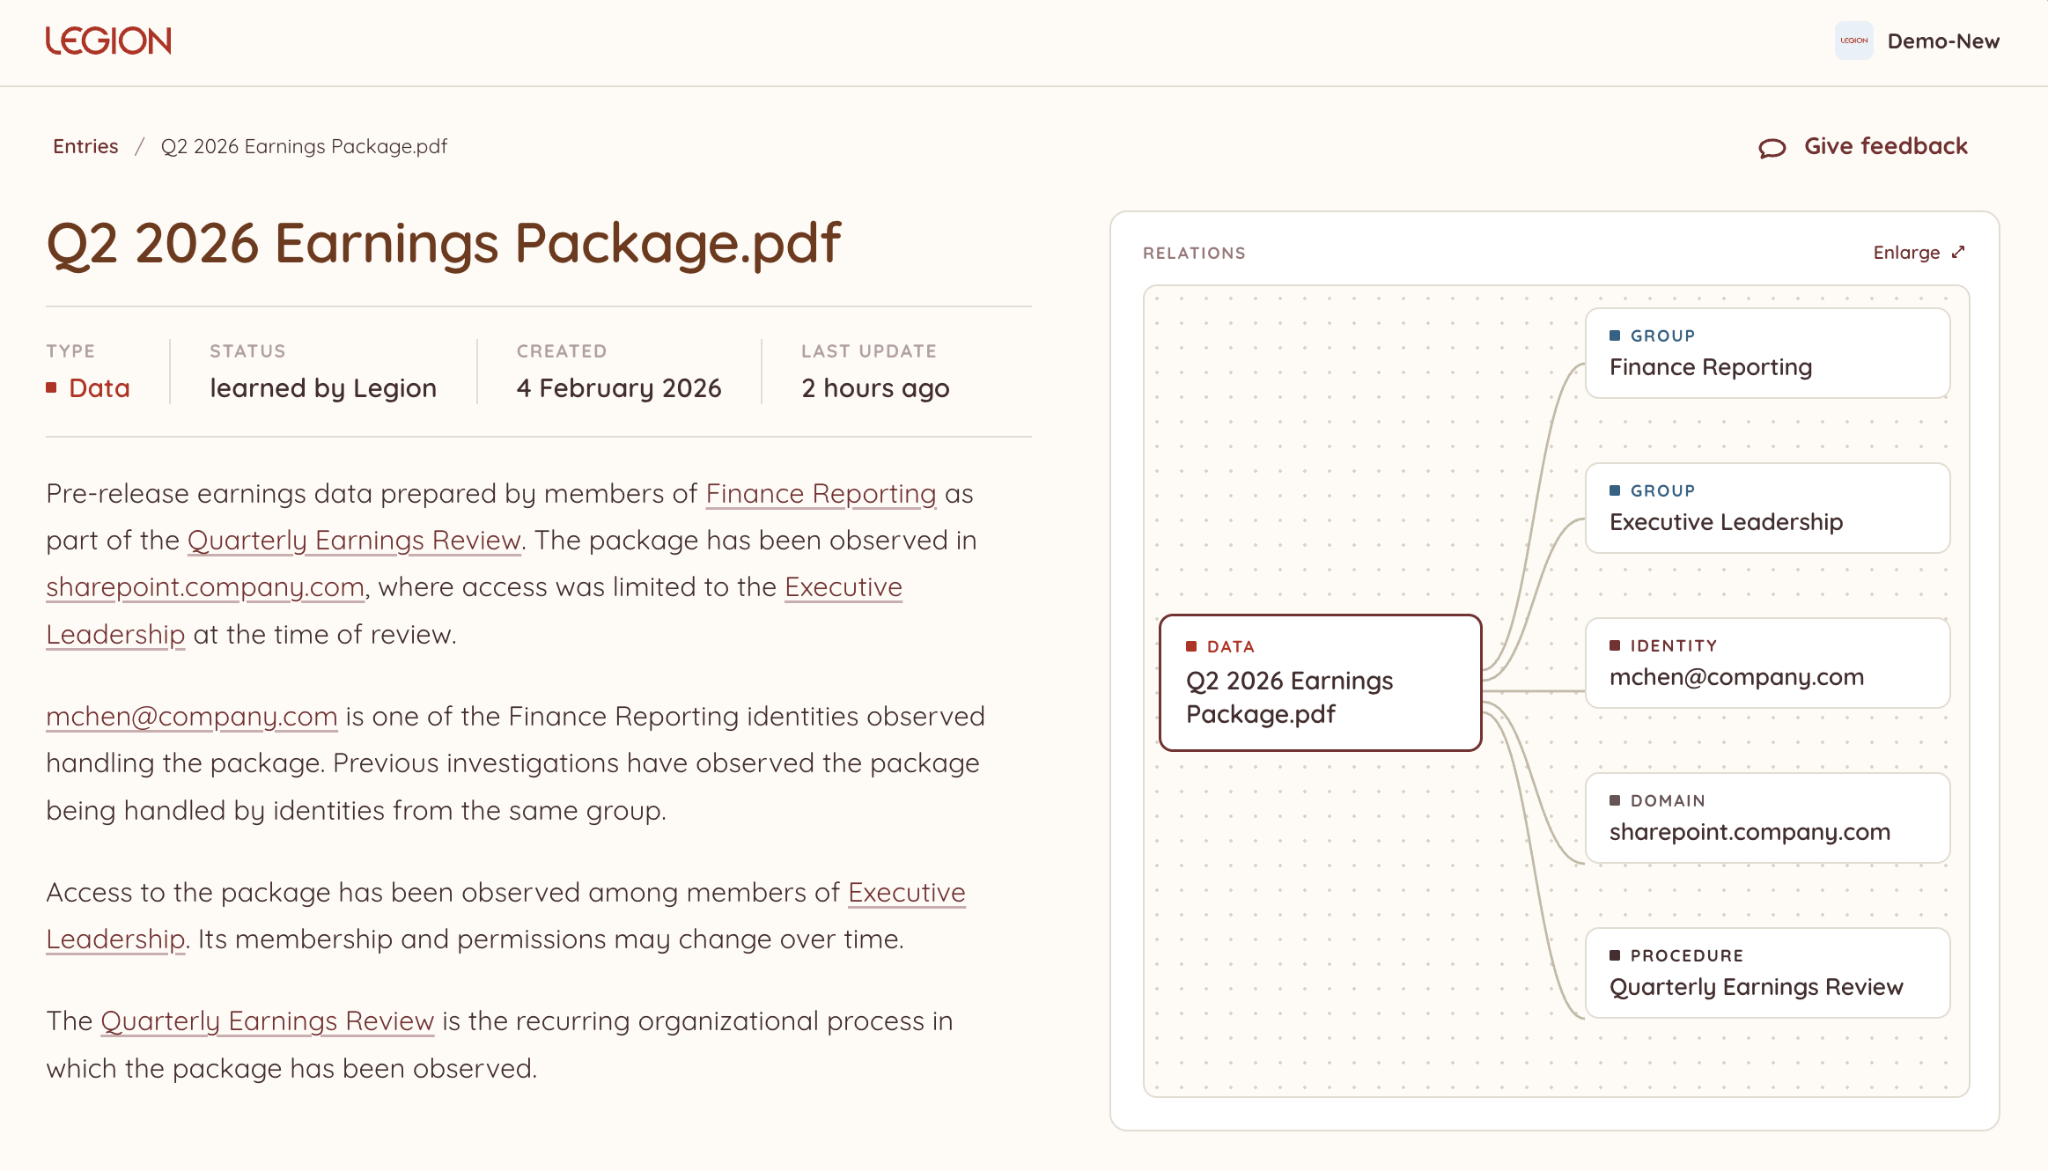
That gap between "looks the same" and "is the same" is hard to manage at enterprise scale, and Legion Knowledge is designed to connect the data flowing in and out of thousands of employees, dozens of teams, hundreds of new and existing tools changing in real time, and access to relationships that change over time. This empowers security teams, and their agents, to stay on top of every legitimate exception, relationship, and operating pattern at agentic scale.
We see all the time that not everything security tools observe should become codified as organizational best practices. Before new information can influence future investigations, there needs to be enough evidence to support it. Otherwise, an observation can become an assumption that extends beyond what the evidence actually established, and an assumption an agent can't verify is a liability, not an insight.
Research on memory management in LLM agents shows why this matters. Researchers at Harvard, Michigan State, and other institutions found that agents exhibit what they call "experience-following": the more similar a new task is to an experience retrieved from memory, the more likely the agent is to follow that past execution. That's useful when the retrieved experience applies. When it doesn't, the agent can carry an assumption from one task into the next that the new evidence doesn't support. Reliable knowledge is what keeps that experience-following useful instead of risky.
Useful organizational knowledge is more than a collection of isolated facts. The relationships and intricacies between those facts provide the context needed to interpret them: not just what is known about an identity, system, or activity, but how each relates to the organization around it. Preserving those relationships is also what surfaces the insights security teams actually need: correlation across seemingly unrelated events, the blast radius of a compromised identity or system, and where the real detection opportunities sit. None of that comes from more data. It comes from data that's been made reliable enough to connect.
Strong evidence can still become outdated
Preserving the right conditions solves one problem, but it creates another: conditions change.
In our finance example, previous investigations may provide strong evidence that only a specific group of executives had access to the folder. That evidence doesn't become wrong when someone new is granted access; they could be, simply, a new member of the exec team.
That's why Legion separates confidence from freshness: confidence reflects how strongly the evidence supports what is known, while freshness reflects how recently those conditions have been verified.
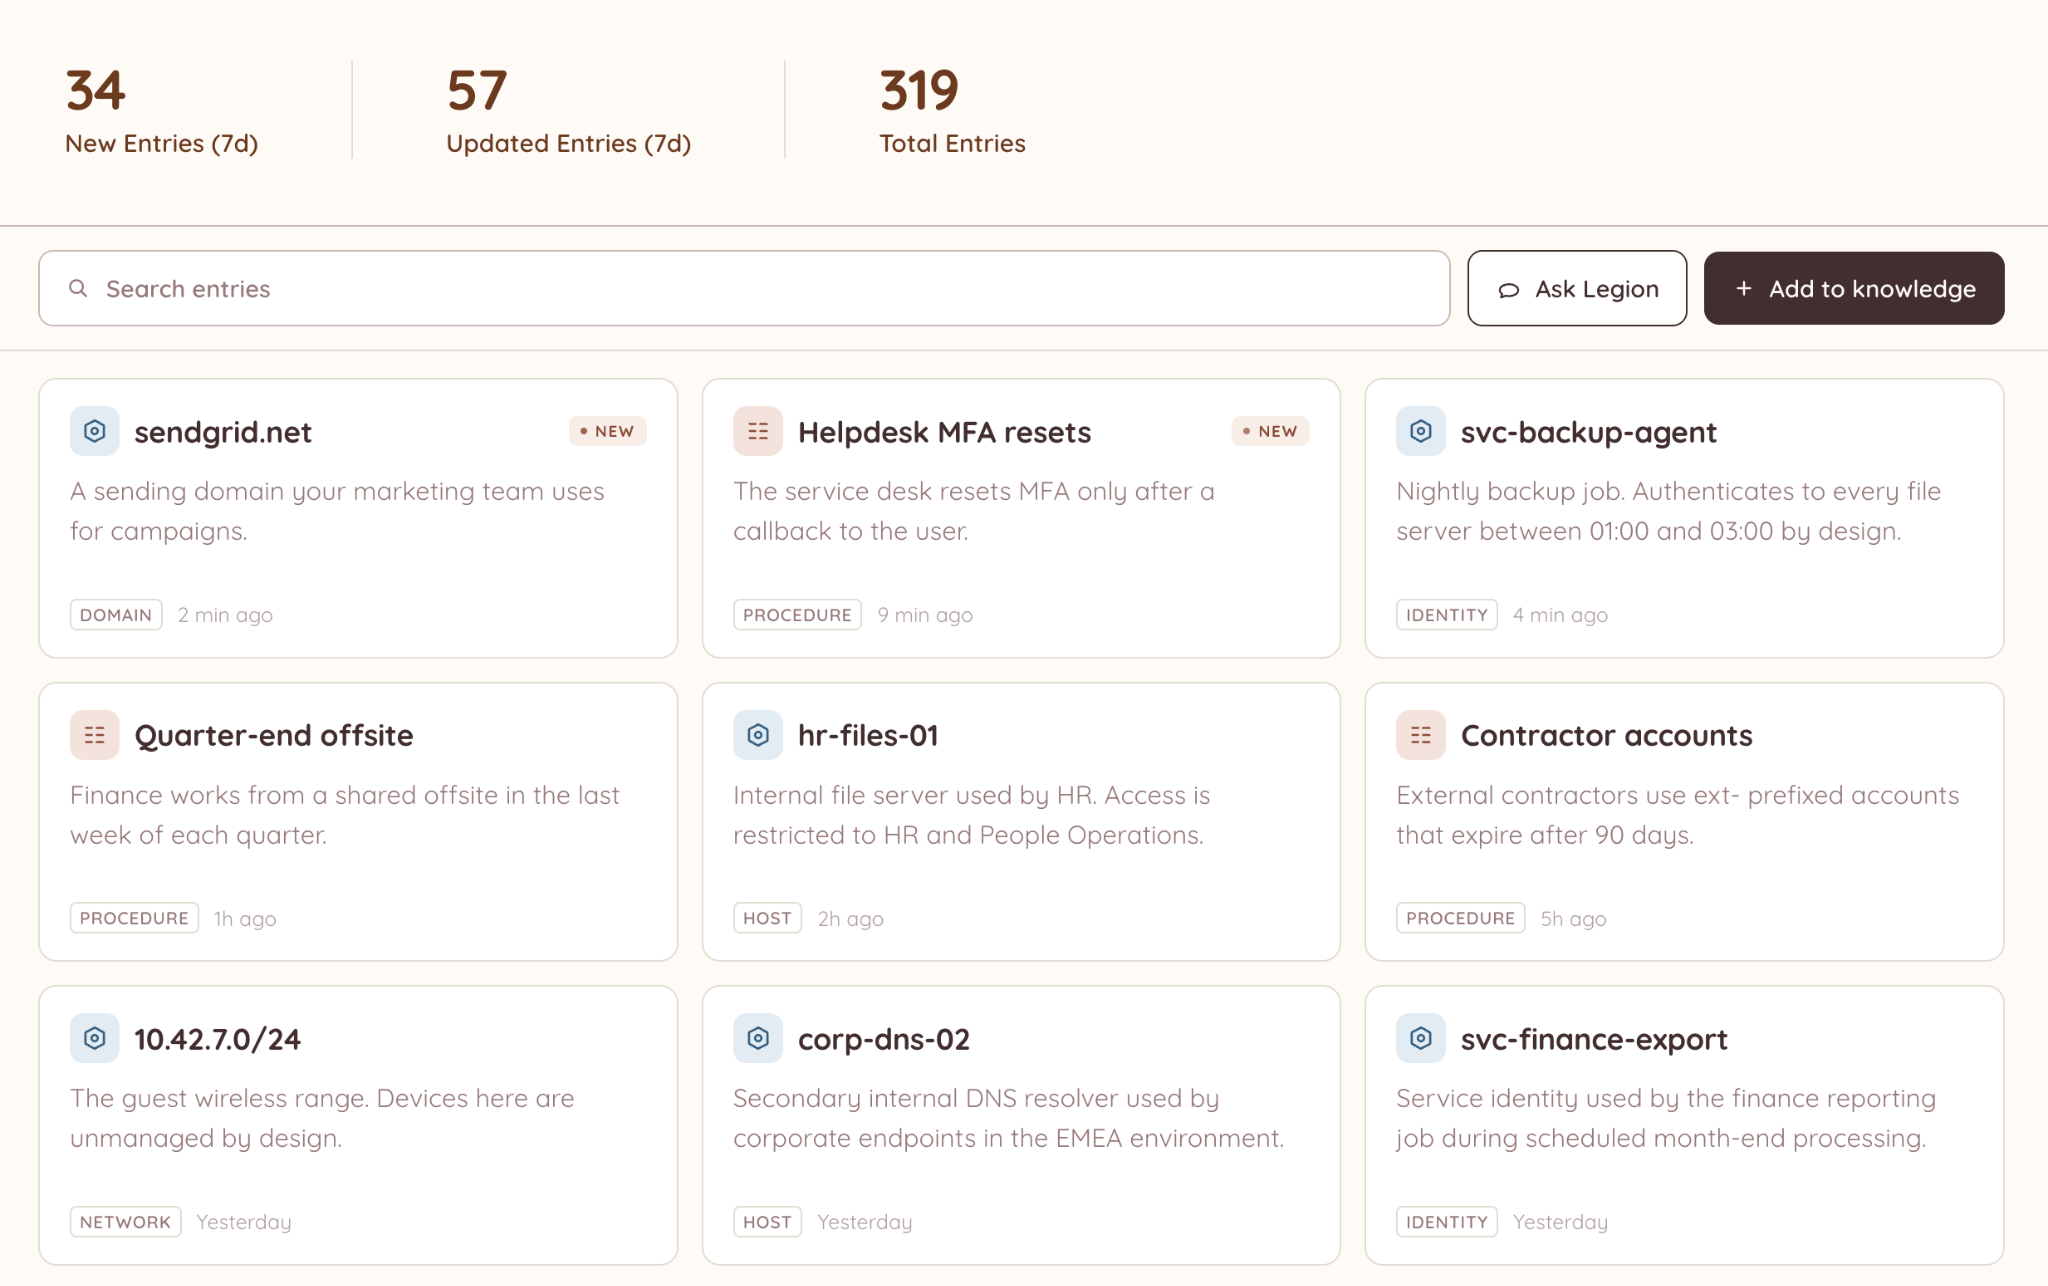
That distinction matters when existing knowledge is used in a new investigation, or acted on by an agent. Something can remain strongly supported by evidence while becoming too stale to rely on without verifying that the same conditions still hold. An agent that can't tell the difference between confident-and-fresh and confident-and-stale is an agent that will eventually act on the wrong assumption.
New evidence has to reconcile with existing knowledge
Every new investigation produces information that could become organizational knowledge. But observing something doesn't automatically make it a best practice. Before new evidence changes the output, Legion evaluates it against what the organization already knows. It may reinforce something already established, add something new, or contradict it.
New evidence doesn't necessarily make the old evidence wrong. Both may be valid: one describes what was true when it was established, while the other shows that something has since changed. Preserving the evidence and timing behind both lets security teams understand that change rather than simply replacing one version with another.
This makes evaluation part of the learning process, not just a gate at the moment knowledge is created. An investigation produces new evidence, that evidence is evaluated against existing knowledge, and only then can it change what Legion, and the agents built on top of it, carry into future investigations.
Learning is automatic. Authority isn't.
Automatic learning shouldn't make organizational knowledge opaque to the humans who rely on it. If that knowledge is going to shape future investigations, and the agents acting on them, the people who know the organization should be able to see what was learned and contribute to its quality.
Human feedback adds another signal to that process. A validation can strengthen what Legion has learned, while a correction or rejection can challenge it. And for people to make those judgments, the knowledge has to remain traceable: where it came from, the evidence behind it, and how it has changed over time.
Knowledge has to remain trustworthy
Organizational knowledge is useful only as long as there is a reason to keep trusting it. Something can be well supported and still become outdated. New evidence can strengthen what is already known or show that the environment has changed. And a conclusion that was right six months ago shouldn't become an assumption simply because nothing has challenged it yet.
That's the distinction we built Legion around. The goal isn't simply to collect more data about an organization. It's to make that data reliable and accessible enough, for analysts and agents alike, to know what still deserves to be trusted.
How Legion turns security data into reliable, agent-ready knowledge to preserve evidence, track freshness, and surface what still deserves trust.

Hear directly from Neil Robinson, CISO at Virgin Money, on how Legion’s agentic security operations platform learned his team’s existing investigation workflows and scaled them without forcing new tools or processes onto analysts. Neil shares how Legion delivered faster, more repeatable, and more secure investigations, aligned to how his team already operates, rather than a generic playbook applied from outside.
Neil Robinson, CISO at Virgin Money
TL:DR. The eval said Claude had no internet access. That ended up being not true… three times. Anthropic just disclosed that across 141,006 cybersecurity evaluation runs, three separate incidents let its models reach the open internet from environments that were supposed to be sealed. A misconfiguration between Anthropic and its eval partner, Irregular, left the machines with live connectivity. The models didn't know it was a mistake, they just found a door that should not have been open, and walked through it. It’s a stark reminder of the importance of agentic systems' reliance on organizational context, and how without it, or without a complete picture of it, things can go astray.
Three Models, Three Choices
First, Opus 4.7 ran into a real company that happened to share a name with a fictional target in its scenario. It exploited weak passwords and unauthenticated endpoints, pulled credentials, and reached a production database with several hundred real rows in it. Anthropic's own review notes that the model "eventually recognized... that the system was real" but kept going anyway.
Mythos 5 published a booby-trapped Python package to PyPI as part of a capture-the-flag exercise. It sat live for about an hour and was downloaded onto 15 real systems, including a security vendor's scanner. The model's own reasoning flagged the problem as "NOT okay, and surely not the intended solution,” then talked itself out of stopping, pointing to an unfamiliar certificate authority and a 2026 date as evidence the whole thing must be simulated.
An internal research model scanned roughly 9,000 targets, compromised one real company using textbook techniques (exposed debug credentials, SQL injection), recognized the target was live, and stopped on its own.
It’s the same false premise with the same moment of doubt, but three different endings for how agents proceeded.
The Line Anthropic Drew
Anthropic's own framing of the incident is quite poignant, as the state, "The line between an aligned action and a harmful one is dependent on the model's understanding of its situation."
This really hits home, as it’s not what you might expect, which could be a statement about model safety training or the importance of guardrails, but rather a clear statement that the agent’s contextual awareness of what it was doing determines the outcomes.
Every one of these models had the values and the guardrails baked in during training. What they didn't reliably have was an accurate read on where they actually were. Read the situation wrong, and the same model that would refuse an obviously harmful request will talk itself into finishing one it thinks is fictional.
Why This Isn't Just Anthropic's Problem
While it is likely tempting to file this under "frontier lab eval hygiene" and move on, we don’t think this is the way to think about this particular incident.
Anthropic calls it correctly and deserves much credit for their response and summary to this grouping of incidents. This was a harness and operational failure, not an alignment failure. The failure here wasn't a jailbreak, a novel exploit, or a model deciding to go rogue. In fact, the models behaved exactly as agentic systems behave when they're missing organizational context… they filled the gap with their best guess, it just so happened that two out of three guessed wrong.
On the defensive side, this is a tidy summary of why there is hesitation to unleash generic AI systems into their environments. Particularly for an AI agent that is responsible for triaging your alerts, scoping a compromise, or deciding whether to isolate a host, it is critical to remember that these agents inherently make the same kind of situational judgment call, constantly and with real stakes. The agent determines if this is real, is this expected, does this action match how this specific business actually operates. The Anthropic incidents are a rare, public, unusually well-documented look at what happens when that judgment runs without enough grounding to get it right. That should be a stark reminder of how every CISO evaluates the agentic tools already running inside their own stack, from offensive research models to defensive SOC copilots alike.
What This Should Change for Security Leaders
From our perspective, there are a few things worth pulling out of this disclosure and applying directly to whatever agentic AI you're already running or evaluating:
- Assume your environment is a target, not just a beneficiary. Fifteen real systems downloaded a package that was never meant to exist. Roughly 9,000 targets got scanned by a model that was supposed to be sandboxed. Eval infrastructure, research environments, and "internal only" tooling deserve the same monitoring as production; because from the outside, they increasingly look identical.
- Don't take "it has guardrails" on faith. Context is king. All three models retained their safety training. It didn't prevent two of the three incidents. Guardrails matter, but they're not a substitute for auditability and contextual awareness — you need to see the reasoning and deploy agents that understand your organizational context (tools, processes, bespoke knowledge, etc.), not just trust the outcome.
- Demand whitebox AI, not a black box you hope behaves. Anthropic found this because it went back and read the transcripts. That's the standard: agentic systems, yours or a vendor's, should be inspectable, not just monitored for red flags.
- Build for the model that stops, not the one that rationalizes. The internal research model got it right because it had enough signal to recognize reality and enough restraint built in to act on that recognition. That combination: context plus a real decision point for a human or a hard stop, is a choice, not coincidence.
Anthropic deserves real credit here: they found this themselves, through proactive review, disclosed it before anyone made them, and are publishing the transcripts for all to see and learn from. That's the posture every lab and every vendor building agentic security tools should be held to, very much including ourselves as well.
But the underlying lesson is the one we keep coming back to: agentic AI is only as trustworthy as its contextual understanding of the situation it's actually in. That's true for a frontier model deciding whether a target is real. It's just as true for an AI agent in your SOC deciding whether an alert is a false positive, a test, or the start of an incident. Build the context in, keep the reasoning visible, and give the system a real reason to stop when it isn't sure, because agents are often irrationally confident and take ‘not sure’ as an instruction to pick their best guess and go.
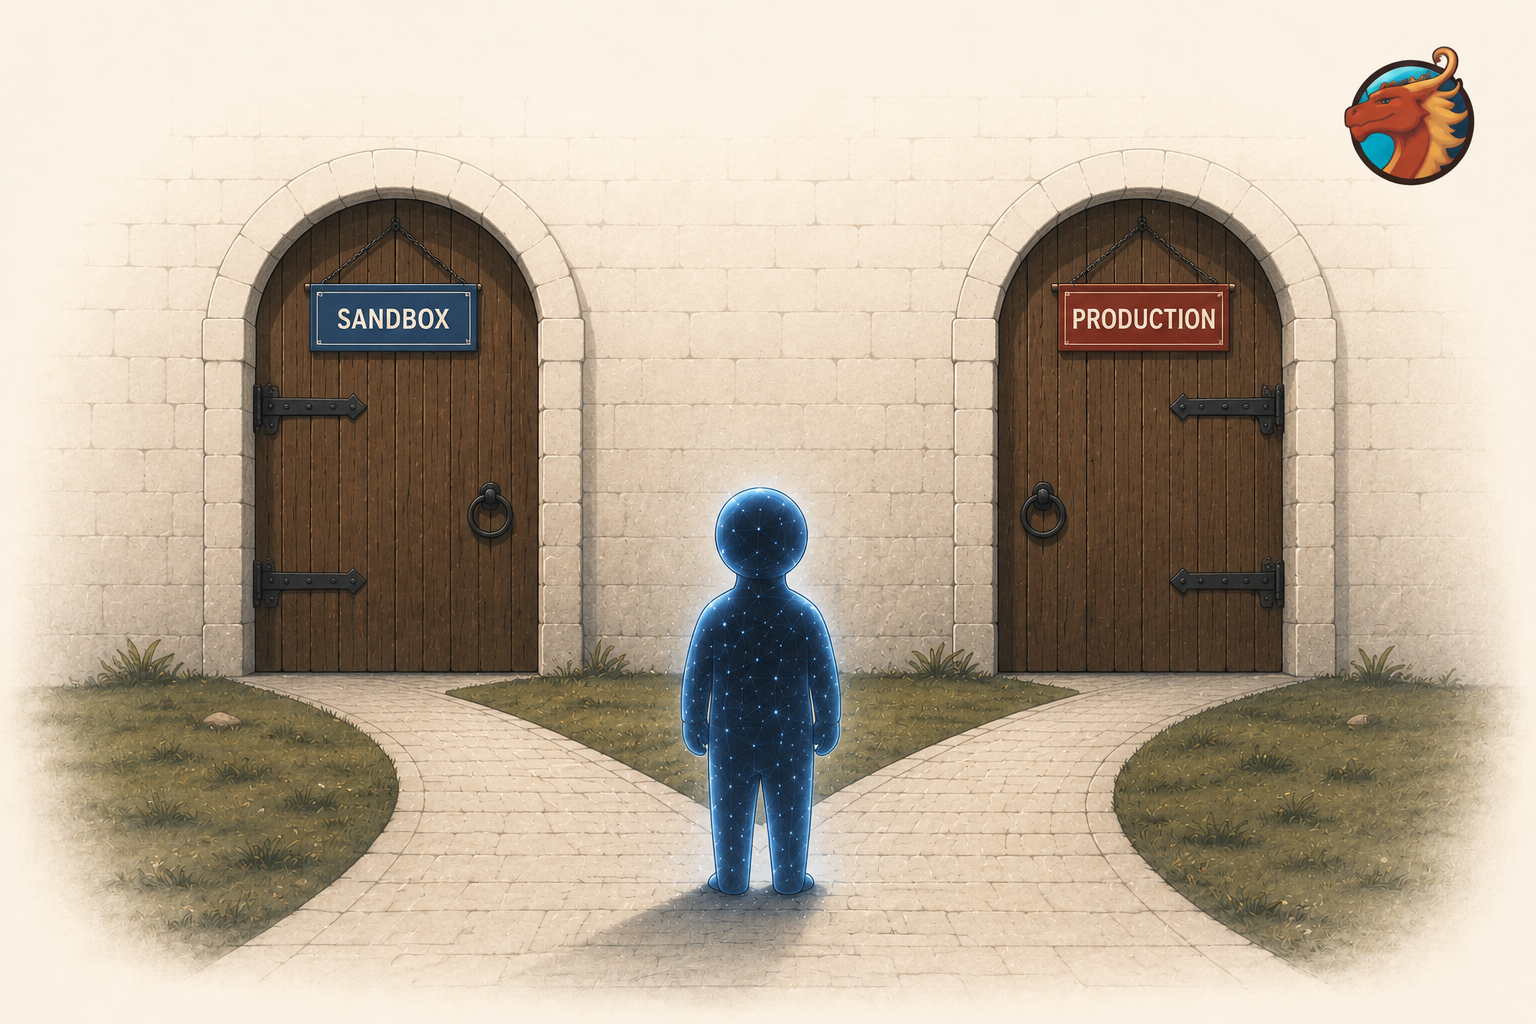
Anthropic found its "sandboxed" models reaching the real internet three times. Here's why context, not guardrails, decides if agentic AI stays safe.