How to Have 24/7 Trust In Your AI SOC
You can trust Legion’s AI SOC solution because it shows live evidence of decision-making and actions taken with real screenshots.


TL;DR: How can you trust that an AI SOC analyst is doing its job the way it's supposed to? As SOC automation takes on more investigation work, being able to verify what the AI actually did becomes increasingly important. The answer is the same as it would be if you asked how you can trust any SOC analyst, AI or human. If you can see proof of work via screenshots from tools, you can trust and audit the work an AI analyst does.
Picture a senior analyst mid-investigation. Eight browser tabs open across CrowdStrike, VirusTotal, Defender, and Microsoft Entra. She's running a hunting query in one window, checking an IP reputation score in another. And somewhere in between, she's documenting. Taking screenshots, copying log entries into a case note, capturing context before it slips away.
The job she's doing is moving across tools, pulling together evidence from a dozen different sources, and building a record that another analyst, or an auditor, or a manager, can actually follow. During her work, this SOC analyst uses and produces documentation.
To be trustworthy in the SOC, AI agents must do the same thing and work to the same standard.
Real Screenshots Are the Most Trustworthy AI SOC Evidence
The reason SOC analysts document their work is that an investigation has always meant showing your work. The summary an analyst writes is the insight they've drawn from what they saw.
Screenshots taken during the work create indisputable evidence, i.e., here is what I found, and here is the proof.

Evidence gathering has always been a core part of the SOC analyst's job and is how you hand off a case without losing context.
How to Trust Your AI SOC
We should hold AI SOC agents to the same standard as we do human analysts.
When a human analyst closes a case, we expect to see their work. The exact screen they reviewed, the exact query they ran, the exact result that informed their decision. A summary of what they found is a claim. The screenshot is the proof.
Most AI SOCs give you API logs and structured JSON responses. However, this is a verdict and a reason rather than trustworthy evidence. The agent processed the alert, evaluated the indicators, and concluded it was malicious.
That's not evidence. A summary can sound confident and still be wrong. Without visual evidence captured at the moment of the decision, you have no way to know what the system actually encountered.
Legion gives you a trustworthy AI SOC by operating differently.
Instead of calling APIs, Legion navigates your source systems directly through the browser, the same way a human analyst would. It opens the actual system, reads the actual screen, and captures a screenshot of exactly what it sees at every step. The summary is the claim. The screenshot is the fact.
That's the standard we believe AI investigations should meet. And it's the only architecture that meets it.
Legion Builds A Trustworthy AI-SOC By Automating Evidence Gathering
Legion Evidence Gathering captures visual proof of every action Legion takes as it navigates your source systems, automatically, in real time.

Take a malware investigation spanning CrowdStrike, VirusTotal, and Defender. Legion opens the originating ticket, reads the case, and begins investigating. As it moves through each tool, it takes a screenshot at every step. The CrowdStrike detection page as it appeared. The VirusTotal result in context. The Defender hunting query and its output. Every interface, exactly as Legion saw it.
By the time an analyst opens the case, the full evidence gallery is already there. Screenshots organized sequentially, labeled by tool, timestamped, and ready to review. Not just a summary. Not just a log. The complete picture: the analysis and the visual evidence behind every conclusion.
And it stays there. Every investigation Legion runs is stored and searchable. When an auditor asks a question, when a peer analyst picks up a handoff, when someone needs to understand why a decision was made, you go back to the session, and everything is right there. Every step. Every screen. Nothing reconstructed. Nothing missing.
Different alert types. Different toolchains. The same complete evidence gallery, every time.
See What Accountable, SOC-Ready AI Looks Like
We've always known what a good investigation looks like. You show your work. You back your conclusions with evidence. You leave a record that someone else can follow. Legion applies that same standard to every automated investigation it runs, without exception and without manual effort. The bar doesn't move because the analyst is an AI. It stays exactly where it's always been.
See Legion Evidence Gathering in action. Request a Demo
Every security team is told to know its adversaries, but for the analysts on the front lines, threat intelligence rarely arrives as known information. Turning feeds, vendor advisories, headlines, or a frantic message from an exec into a confident answer about real risk to the enterprise is (one of many of) the hard parts, and it's where a lot of the work (and frustration) lives for security professionals.
In this piece, I’ll aim to look at why that gap persists, what it looks like during a real incident, and how we think agents and analysts can close it together.
Why threat intelligence is so hard to act on
Threat intelligence comes in layers, and each one decays at a different speed. Indicators of compromise like hashes, IPs, and domains can be among the easiest to consume, but attackers rotate them constantly. Tactics and techniques last longer, but they're harder to engineer into a detection rule because they describe behavior rather than a specific artifact you can search for. Emerging campaigns (PHP, anyone?) sit on top of both, mixing new infrastructure with familiar techniques in ways that rarely match what the detection stack was built to catch.
The real challenge is relevance and translation to the different stakeholders across an enterprise. While a feed can tell you that a group is exploiting a specific vulnerability, it can't tell you whether you run the affected software, whether it's exposed, whether anyone has already touched it, or what it connects to. Analysts fill that gap by hand, pivoting across the SIEM, EDR, asset inventory, vulnerability scanner, and cloud console, and that work competes with an alert queue that never stops. And now, as attackers use AI to operate at greater scale and speed, that backlog grows faster than any team can possibly manage by hand.
What the recent PHP incident looked like from the inside
The recent PHP vulnerabilities CVE-2026-109618 and CVE-2026-109619 shows how this plays out. The advisory came out, proof-of-concept code followed quickly, and within hours security teams everywhere were asking and being asked… How exposed are we?
Answering this type of question is rarely one query. Security pros first had to find every system running PHP, including the affected versions and configurations, which usually means reconciling an outdated asset inventory with scanner results that are only as fresh as the last scan. Then they have to work out which systems are internet-facing, which typically sit behind a WAF, and are owned by teams that security likely doesn't talk to every day. Homegrown applications and legacy servers are the hardest, because they often live outside the tools that would report them.
From there, the work splits into parallel tracks. Threat hunters search logs and endpoint telemetry for signs of exploitation using whatever indicators have been published. Detection engineers write and tune new rules. Vulnerability management chases patch owners and tracks exceptions. Each track lives in a different tool with a different owner and cadence, and the whole process has to keep firing as new indicators and exploit variants appear over the following days. Most teams hold it together with tickets, spreadsheets, and a lot of Slack messages, if at all. And it’s not even their fault! Especially in a crisis, if something is confidently labeled as an endpoint issue but it really is an identity problem, it’s very easy to get skipped over, marked as benign, or not correlated / communicated to other departments. It’s just full-steam ahead.
Then comes the question from the top
While all of that is happening, the security analyst needs an answer for the CISO, who needs an answer for the CEO, who in turn needs one for the board. Leadership doesn't have much use for a list of hosts, they want to know whether the business is at risk, what was exposed, whether anything was compromised, and when the problem will be closed.
Assembling that answer means stitching together findings from every parallel track, each with its own definitions and level of confidence. The analyst summarizes for the security manager, who summarizes for the CISO, who translates it again into business terms for the executive team. Every hop loses detail and adds delay, and by the time the summary reaches the board, the facts underneath it have often changed. Security leaders end up reporting effort, like patches applied and rules written, because measuring actual risk reduction quickly is so hard.
How agents and analysts could (should?) share the work
At Legion, we believe the answer isn't yet another feed or another dashboard, but rather it’s a coordinated set of agents (some may call this a legion) that handles the repetitive, cross-tool work of threat intelligence alongside the analysts who own the judgment calls.
In practice, that means agents that operate the tools your team already uses, through APIs and MCP, and through the browser for homegrown and legacy systems that have neither. When a new threat lands, agents can find affected assets, check exposure, hunt for indicators and techniques across telemetry, and enrich every related alert with that context, so scattered signals become a single case. Because agents investigate every signal rather than just the top of the queue, they catch attacker activity that's spread thin across many low-priority alerts. This is one of the many use cases that our customers are using DragonClaw for in production today.
Those agents should also learn how your team really works. In a crisis, analysts rarely have time to open the runbook or follow every step to a T. They act on a hunch from a similar case last year, skip the query they know will come back empty, or already know which detail the CISO will ask about first and pull it before anyone asks. That instinct is some of the most valuable knowledge in a security enterprise. When agents learn from recorded investigations and the decisions analysts actually make under pressure, they capture those shortcuts too, so the next incident moves at the speed of your best analyst's instincts where those are the right path, and creates new, optimal paths for others.
From headline to boardroom
I don’t believe it’s ambulance chasing, but rather a known fact to suggest that the next incident like this one is already coming. From what we see, the teams that handle it well will be the ones who can move from headline to exposure to action to a clear executive answer in hours instead of days. That's the shift we're building, agents that carry the cross-tool work at machine speed, and analysts who spend their time on the decisions that actually reduce risk.

Using the recent PHP vulnerabilities as an example, see why threat intel is so hard to act on and how agents and analysts can close the gap together.
TL;DR: DLP tools generate more alerts than analysts can properly investigate, so many get closed based on whatever the alert shows. DLP alert automation cuts DLP alert fatigue by taking on the work that comes after an alert fires. Legion learns how your team investigates, gathers context from across your systems and applies that approach to every alert.
DLP alert fatigue (why DLP alerts are everywhere)
You already know that DLP is one of the noisiest sources of alerts. DLP alerts fire whenever a user performs an activity that matches the criteria of a rule in a DLP policy, and the organization has incident reporting configured to turn those matches into alerts. Every email, file share, upload, print job and USB copy is a chance for a rule to match, so in an organization of any real scale, the alerts Never. Stop. Coming.
Each of those alerts asks the analyst the same underlying questions: Did sensitive data actually leave the organization, or was it about to go somewhere it shouldn't? If it did, was that an honest mistake, a legitimate business action, or something malicious?
Answering those questions accurately requires a genuine investigation, but when dealing with a noisy alert cannon, not every alert is able to be properly investigated, resulting in a ton of false-positives, analyst burnout, and potentially even false-negatives. That’s where DLP alert automation comes in.
What is DLP alert automation?
DLP alert automation means using automated tools to do some or all of the work after a DLP alert fires. That includes pulling context, looking at the content that matched, deciding whether it’s a real risk and acting on it.
There are two main approaches to DLP alert automation.
- Rule-based automation, such as SOAR playbooks, follows predefined workflows. It can enrich alerts and take actions like opening a ticket or disabling an account, but only along paths someone has configured in advance.
- Agentic tools work through each alert the way an analyst would, reach a verdict and pass the high-risk or unclear cases to a person.
What a DLP investigation actually looks like
The details vary from one DLP platform to another and from one organization to another, but the shape of the investigation is mostly consistent.
- Find the alert
- Read what triggered it
- Look at the destination and the action
- Review the content itself
- Add user context
- Decide and act
- Tune the policy
Whether any of these steps actually presents a risk depends on information most DLP tools in isolation don’t have, because it’s scattered across the enterprise. Identity data sits in your IdP, device posture sits in your EDR, employment status and upcoming departures sit in your HR system, and the history of what this person normally does is spread across months of logs and cases in several different places.
Some of it may not even be available at the moment the alert is being reviewed, so the analyst is left with two imperfect choices.
- They can investigate the alert fully, pivoting between various consoles to assemble the full picture → which stalls the investigation while the queue keeps growing
- Perhaps more frequently, they make the call based on whatever the DLP alert shows them → likely the alert gets closed as a false positive or benign business activity because nothing in front of them suggests otherwise
Most organizations have already invested heavily in DLP. Their teams have spent years writing policies, defining sensitive information types, mapping where regulated data lives and deciding which activities should trigger an alert. What’s missing is everything that happens after the alert fires.
Every organization investigates DLP alerts a little differently, shaped by its own processes, tools and people. Some teams have a well-honed approach built up over years, while others are still working out what a good investigation should look like, and most are somewhere in between.
Legion meets you wherever you are. It learns how your team already looks into DLP alerts and signals, then helps fill the gaps and refine the process as it sees what works, and carries it out consistently on every alert at machine speed from alert through response and remediation.
How Legion automates DLP alert investigations
When an alert fires, Legion reads the policy and rule that matched, looks at the destination and the action, checks the content, and then goes out to gather the context that the DLP tool can't provide on its own.
To investigate DLP properly, security analysts (or their agentic counterparts) need cross-system context. They also need the context of your business itself, meaning your trusted partner domains, your sanctioned storage locations, the teams that routinely handle regulated data, and the people who need to hear about a confirmed incident. None of that lives inside the DLP tool, which is precisely why a DLP-only approach struggles and why Legion is designed to connect to the systems where that context actually lives, whether they have clean APIs or not.
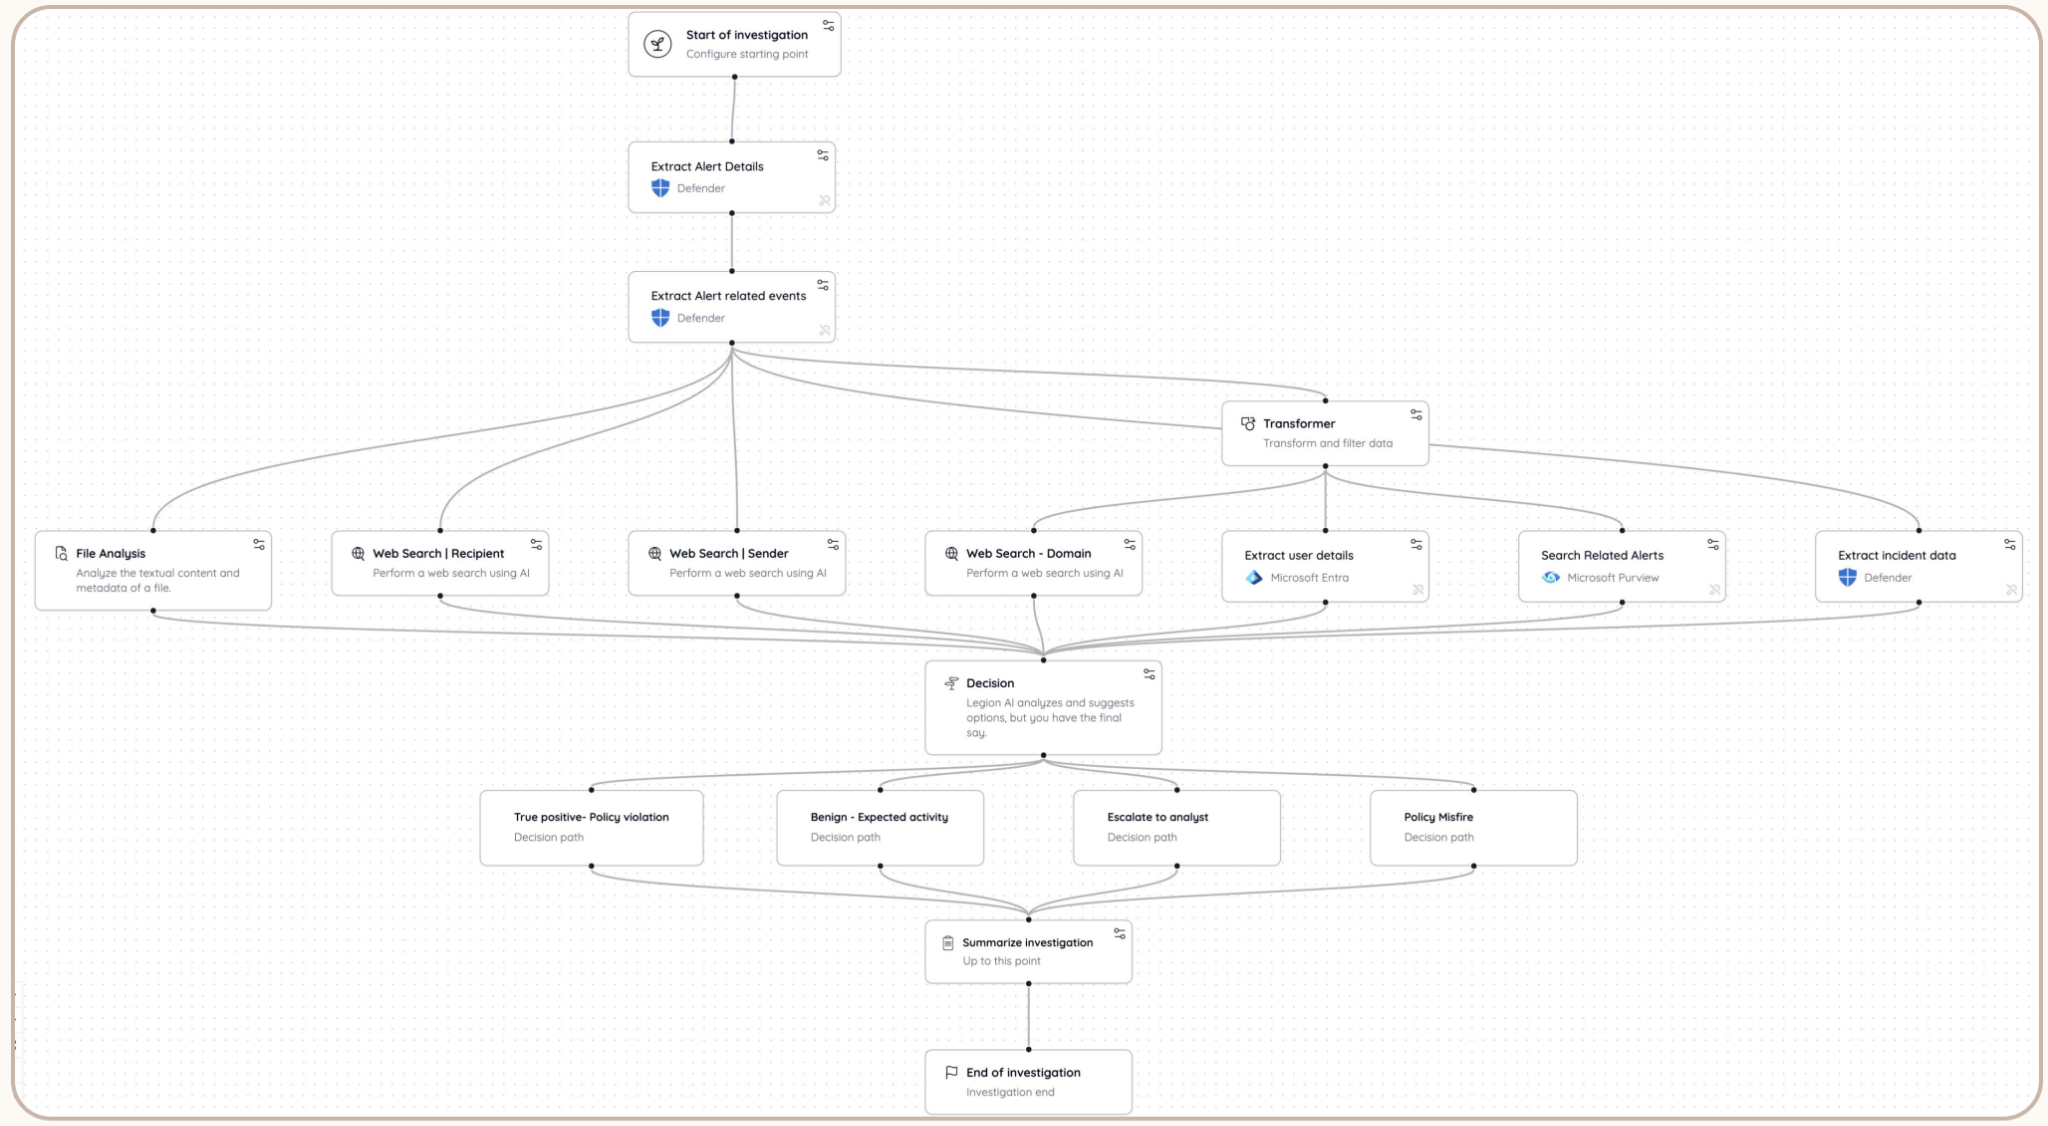
This is also what changes the value of the DLP tool itself. On its own, a DLP platform is very good at seeing things like where and when sensitive data is moving, and telling you which rule it matched, but it has no way to judge whether that matters.
When Legion operates the DLP tool, opening the alert, reviewing the matched content, and taking actions inside the console such as revoking a sharing link or applying a label, that DLP tool (or tools) effectively gains an advanced-level brain. Every detection now arrives with the identity, endpoint, HR and business context needed to make a decision, and every decision can be acted on right where the data lives.
The policies your team has spent years building finally get the judgment they were always missing, so the DLP investment starts producing answers instead of just alerts. For situations where a rule keeps generating the same false positive, that pattern is visible, so tuning the policy becomes a decision rather than a guess.
Because Legion learns, understands, and optimizes your team's logic rather than implementing a generic playbook, its conclusions look like the ones your *perfect* analyst would reach.
Your expertise, at the scale of your alert queue
DLP alerts aren't going to slow down, and we shouldn't expect them to. In fact, we should all expect them to pick up. The real problem has always been that a thorough investigation depends on context spread across a half-dozen tools and on judgment that lives with a few experienced people on your team.
Legion brings DLP alert automation to the processes your team already follows. It learns how your organization investigates DLP, connects to the identity, endpoint, HR and business context that the DLP tool can't see, and applies the optimal approach to every alert in the queue.
Your analysts get their time back for the cases that genuinely need a human, and every DLP alert gets the investigation the perfect analyst would give it.

Legion brings DLP alert automation to your existing tools, adding the context and judgment needed to investigate every alert, identify real threats, and take action.
Legion’s agentic security platform is built on a simple idea: your team knows how to investigate, but it is knowledge that is one of the most valuable and unique things your SOC has. Legion captures how your analysts work, all the way from an alert, to the steps they take to the evidence they gather and the reasoning behind each verdict, and turns it into agentic investigations that run the same way every time.
But that context should not stay locked inside a single console for knowing analysts. Security teams increasingly do their thinking in AI assistants like Claude and ChatGPT, whether they're drafting an incident summary, preparing for a leadership update or trying to remember whether they've seen an indicator before. That's why we offer our customers the Legion MCP server, which connects those assistants directly to your Legion data through the Model Context Protocol. With this, security teams can ask questions about their investigations in plain language, from the tools they already use every day, and get answers grounded in what Legion actually did.
What your team can ask
Once Legion is connected, an analyst or security leader can pull up the full story of an investigation without leaving their conversation. They can find sessions by title, summary or entity, filter them by status, decision, workflow, analyst or date, and walk through each step along with the verdict it reached. They can also see which workflows and use cases are running, check how much of their monthly action allowance has gone to guided versus autonomous runs, and get answers about Legion itself from our documentation, with links back to the source pages.
In practice, that means questions like these:
- "Summarize our Legion sessions from the last 24 hours: what failed, what's still active, and which were decided true positive."
- "Open our most recent phishing investigation and walk me through each step, the entities it found, and why it reached its verdict."
- "Have we investigated 203.0.113.42 before? List every session that mentions it, with dates and outcomes."
- "Which workflows ran most last month, and what use case does each belong to?"
- "How close are we to our action limit this month? Split it by guided and autonomous runs."
- "How do I set up a Jira poller so new tickets trigger a workflow? Cite the docs."
Because the answers come from your own investigations, the assistant isn't guessing at how your SOC handles an alert. It's reporting what your team's process actually found, which makes it far more useful for shift handoffs, executive briefings and the everyday question of "have we seen this before?"
Built with security teams in mind
We know that connecting security data to an AI assistant raises fair questions, which is why our MCP server starts by being conservative, gaining your trust as it goes. It's read-only, which means it can't create, change or delete anything in Legion, and it can't run workflows, skills or agents. Each person connects from their own assistant and signs in with their own Legion account, so every request runs as that user and is checked against their Legion role. Nobody sees more through Claude or ChatGPT than they could already see in Legion.
Admins stay in as much control as they want, throughout deployments. MCP access is turned off until an admin enables it for the organization, and it can be switched off again at any time. Individual users can disconnect Legion from their assistant whenever they like, and admins can revoke a specific user's sessions, which ends that person's MCP access within about a minute.
Getting started
Setup takes just a few minutes. Legion has always been about capturing the way your team investigates so that expertise can scale. With MCP, that expertise travels with your team, into the assistants where more and more of their work already happens. If you’d like help in configuring this or to learn more, please reach out to [email protected].

Connect Claude and ChatGPT to Legion via MCP and ask about your investigations in plain language, with read-only access scoped to each user’s role