How Knowledge Management Impacts Security Investigations
How Legion turns security data into reliable, agent-ready knowledge to preserve evidence, track freshness, and surface what still deserves trust.

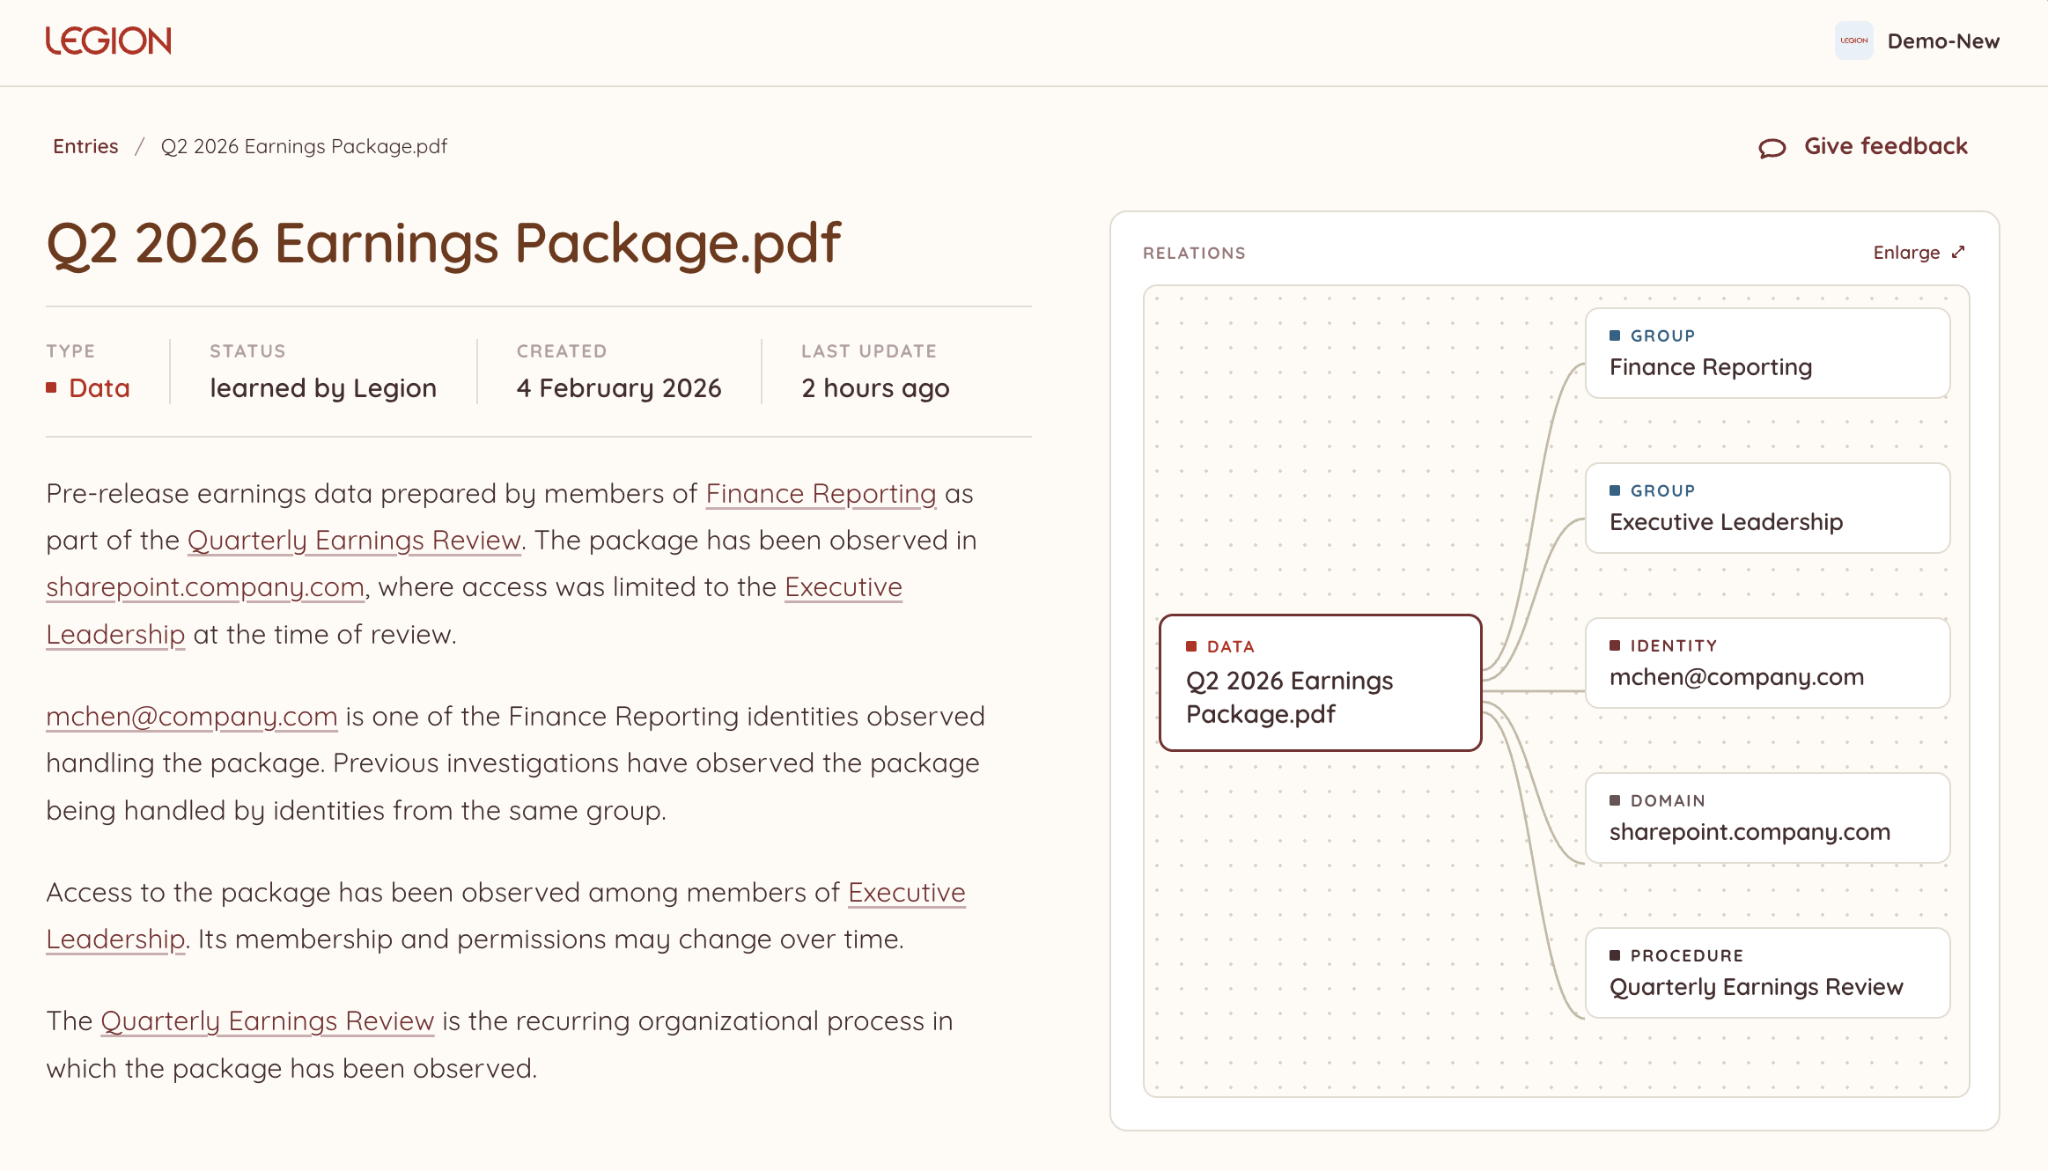
Security investigations rarely start with all the context needed to reach the right decision, and we see plenty of examples of this in real environments. Let’s look at an anonymized but recent example. Every quarter, a publicly traded enterprise’s finance team uploads the company's still-unreleased earnings package which consists of revenue, forecasts, and results that won't go public until earnings day to a restricted SharePoint site for executive review. The package contains sensitive financial information so the upload triggers a DLP alert for review. Pretty standard stuff.
That alert triggered an analyst investigation where the incident response team confirmed the uploader was indeed a part of the reporting team, the destination was the approved site, and access was limited to only the small group of executives who were supposed to see it. Nothing dangerous, so it was safely closed as benign. This single investigation established the conditions that made the activity safe: who was expected to upload the file, where it was supposed to go, and who was supposed to have access.
But the lingering question is… what should be carried forward and/or codified from that investigation? This question is one that we’re obsessed with answering and helping our customers address.
With Legion, instead of carrying forward a single verdict from a single investigation, enterprises can uniquely capture the conditions that each investigation establishes together with the underlying and complementing evidence behind them. On a continuous basis. This holistic view matters, particularly in today’s world, because the same activity type doesn't always mean the same thing, and this is a constantly moving target as environments change. Using our ‘finance team uploading earnings files into SharePoint’ example, one of the conditions that was met, who had access to the folder, can change very quickly. So perhaps the next time, the package is the same, the site is the same, the timing is the same, but the folder may have been shared with an external account or a new unverified user.
The challenge isn't collecting more data. Most enterprises already have plenty of it, scattered across identity providers, endpoints, SaaS apps, and past investigations. The challenge is turning that raw data into knowledge that's reliable enough, and accessible enough, for agents to actually reason over: preserving what made something true, connecting it to the organizational context around it, and continuously testing whether it still holds as the organization changes.
Knowledge needs conditions, not conclusions
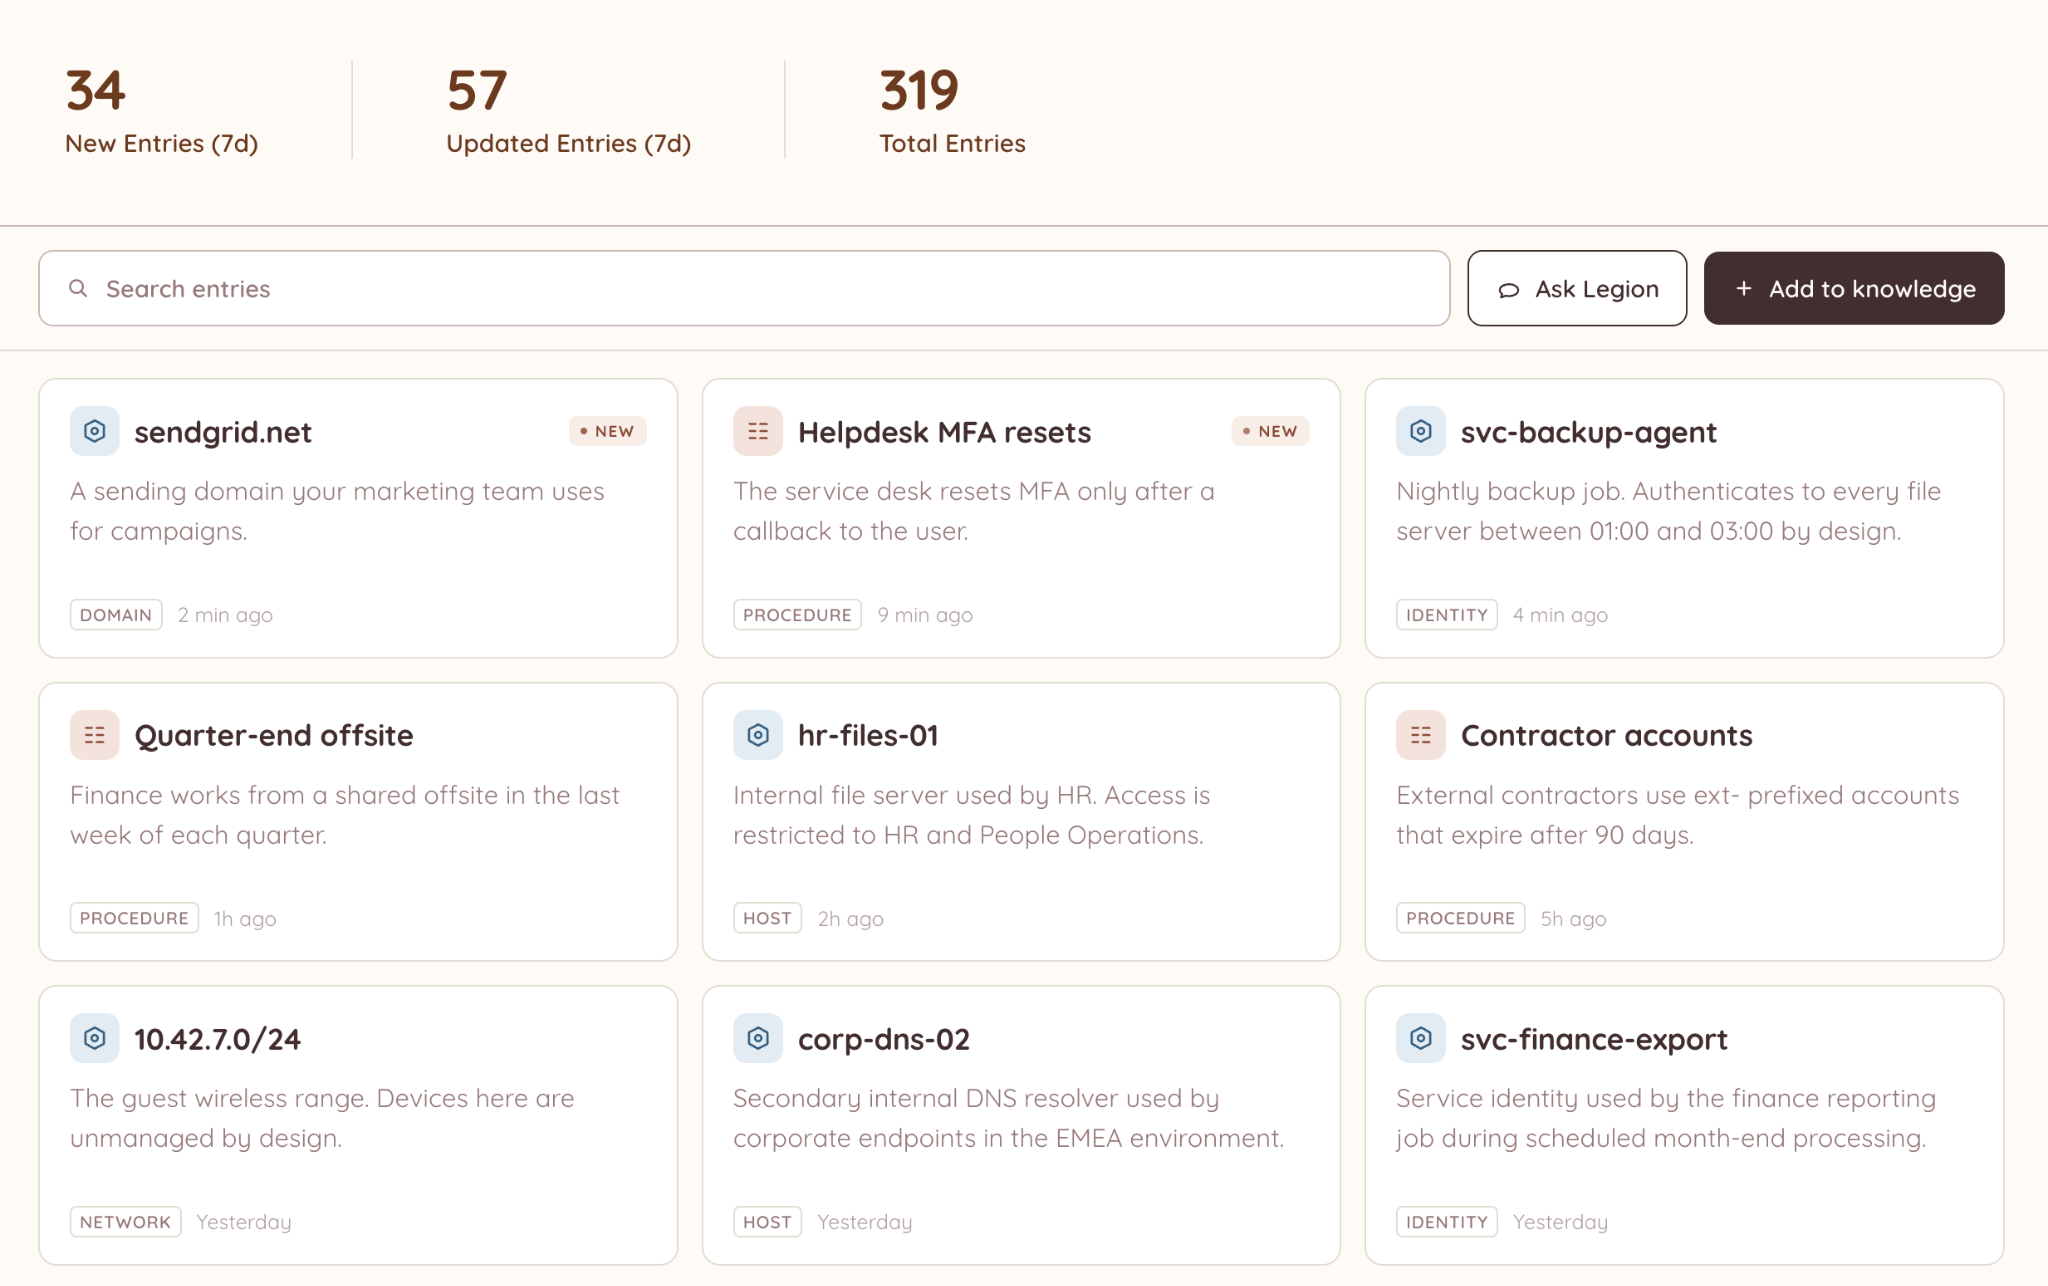
That's why Legion represents organizational knowledge and context as a continuously evolving model that connects identities, teams, systems, data, access, behaviors, and the evidence establishing how they all relate to one another.
Legion’s knowledge isn't built from investigations alone. Legion brings information from across the environment, including identities, access, systems, infrastructure, and the relationships between them, into the same layer. Past investigations add another important source, giving Legion an accumulated history from day one: what analysts already checked, what they found, and the evidence that supported those decisions.
Raw data on its own doesn't tell an agent much. An identity, a login, a file upload, a network connection, in isolation, are just data points. What makes this usable is the relationship it has to everything around it. That's what turns data into knowledge an agent can actually act on: not just what happened, but who was involved, what it touched, what normally follows it, and what it means if it doesn't.
That gap between "looks the same" and "is the same" is hard to manage at enterprise scale, and Legion Knowledge is designed to connect the data flowing in and out of thousands of employees, dozens of teams, hundreds of new and existing tools changing in real time, and access to relationships that change over time. This empowers security teams, and their agents, to stay on top of every legitimate exception, relationship, and operating pattern at agentic scale.
We see all the time that not everything security tools observe should become codified as organizational best practices. Before new information can influence future investigations, there needs to be enough evidence to support it. Otherwise, an observation can become an assumption that extends beyond what the evidence actually established, and an assumption an agent can't verify is a liability, not an insight.
Research on memory management in LLM agents shows why this matters. Researchers at Harvard, Michigan State, and other institutions found that agents exhibit what they call "experience-following": the more similar a new task is to an experience retrieved from memory, the more likely the agent is to follow that past execution. That's useful when the retrieved experience applies. When it doesn't, the agent can carry an assumption from one task into the next that the new evidence doesn't support. Reliable knowledge is what keeps that experience-following useful instead of risky.
Useful organizational knowledge is more than a collection of isolated facts. The relationships and intricacies between those facts provide the context needed to interpret them: not just what is known about an identity, system, or activity, but how each relates to the organization around it. Preserving those relationships is also what surfaces the insights security teams actually need: correlation across seemingly unrelated events, the blast radius of a compromised identity or system, and where the real detection opportunities sit. None of that comes from more data. It comes from data that's been made reliable enough to connect.
Strong evidence can still become outdated
Preserving the right conditions solves one problem, but it creates another: conditions change.
In our finance example, previous investigations may provide strong evidence that only a specific group of executives had access to the folder. That evidence doesn't become wrong when someone new is granted access; they could be, simply, a new member of the exec team.
That's why Legion separates confidence from freshness: confidence reflects how strongly the evidence supports what is known, while freshness reflects how recently those conditions have been verified.
That distinction matters when existing knowledge is used in a new investigation, or acted on by an agent. Something can remain strongly supported by evidence while becoming too stale to rely on without verifying that the same conditions still hold. An agent that can't tell the difference between confident-and-fresh and confident-and-stale is an agent that will eventually act on the wrong assumption.
New evidence has to reconcile with existing knowledge
Every new investigation produces information that could become organizational knowledge. But observing something doesn't automatically make it a best practice. Before new evidence changes the output, Legion evaluates it against what the organization already knows. It may reinforce something already established, add something new, or contradict it.
New evidence doesn't necessarily make the old evidence wrong. Both may be valid: one describes what was true when it was established, while the other shows that something has since changed. Preserving the evidence and timing behind both lets security teams understand that change rather than simply replacing one version with another.
This makes evaluation part of the learning process, not just a gate at the moment knowledge is created. An investigation produces new evidence, that evidence is evaluated against existing knowledge, and only then can it change what Legion, and the agents built on top of it, carry into future investigations.
Learning is automatic. Authority isn't.
Automatic learning shouldn't make organizational knowledge opaque to the humans who rely on it. If that knowledge is going to shape future investigations, and the agents acting on them, the people who know the organization should be able to see what was learned and contribute to its quality.
Human feedback adds another signal to that process. A validation can strengthen what Legion has learned, while a correction or rejection can challenge it. And for people to make those judgments, the knowledge has to remain traceable: where it came from, the evidence behind it, and how it has changed over time.
Knowledge has to remain trustworthy
Organizational knowledge is useful only as long as there is a reason to keep trusting it. Something can be well supported and still become outdated. New evidence can strengthen what is already known or show that the environment has changed. And a conclusion that was right six months ago shouldn't become an assumption simply because nothing has challenged it yet.
That's the distinction we built Legion around. The goal isn't simply to collect more data about an organization. It's to make that data reliable and accessible enough, for analysts and agents alike, to know what still deserves to be trusted.
➤ Problem: A backlog of tens of thousands of security alerts and overwhelmed analysts who could not keep up.
➤ Solution: Legion's agentic SOC automation, which learns existing SOC workflows and takes over routine investigations transparently.
➤ Outcome: Legion's agentic SOC automation processed 30,000 backlogged alerts for Virgin Money in under two months, leading to a 60% reduction in their alert backlog.
Neil Robinson, CISO at Virgin Money (a major UK financial services brand and retail bank), was facing a familiar SOC problem: a massive volume of alerts overwhelming their security operations team.
Protecting a large, high-profile attack surface meant that Virgin Money had to deal with a backlog of around 50,000 security alerts. This placed immense pressure on their ~200-person security team.
Within two months of deploying Legion’s Agentic Security Operations Platform to automate repetitive SOC workflows, Virgin Money had reduced its alert backlog by more than 60%.
Alert reduction was the SOC automation benefit Robinson wanted. Legion's other core advantage was that it let his team automate existing security workflows without forcing his SOC to redesign its operations.
“Legion has just completely transformed the way I think about automation. You take your existing operation and really just 10x it.” - Neil Robinson, CISO at Virgin Money
A 200-person SOC with a 50,000 alert backlog
Virgin Money relies on a security organization of around 200 people to protect their bank and its more than 6 million customers from cybersecurity threats.
Like many modern financial institutions, Virgin Money offers a huge range of digital banking services from current accounts to mortgages. They also provide customers with in-person services through branches and hubs.
The digital infrastructure required to support this broad business creates a large attack surface and a huge volume of security alerts.
Many of these alerts are low-value or false positives. Yet they still drain analyst attention that could be better spent on higher-value security investigations. The result was the alert fatigue that security teams know all too well. Too many alerts, too little time.
To solve alert fatigue, Virgin Money wanted to reduce the time analysts spent on low-value alerts. But they needed automation their analysts could inspect and trust.
Transparent SOC automation
Robinson estimates that Virgin Money reviews around 100 new security solutions each year, many of them focused on automation. And for each, integrity and security are top concerns.
More specifically, Robinson wanted whatever solution Virgin Money chose to guarantee that:
- Automation inside a security operation behaves predictably.
- Analysts can see what the automation is doing and why it reached a given decision.
- The system can be trusted with sensitive security workflows.
Robinson was immediately impressed that Legion uses vision models to watch how experienced analysts work on screen, so Virgin Money did not have to define every workflow by hand.
Legion can be deployed on an engineer's desktop to observe the sequence of actions in an investigation and turn that activity into a visual workflow.
“It feels a little bit like magic when you first turn it on, but then it gives you this really nice workflow diagram where you can see exactly what it's doing.” - Neil Robinson, CISO at Virgin Money
Legion did not require Virgin Money to replace its existing SOC processes. Instead, the platform learned how analysts already handled alerts and turned those operating patterns into repeatable automated workflows.
Using vision models combined with other methods to observe how analysts investigate alerts, Legion helps enterprises like Virgin Money either codify SOC processes or optimize them into visual agentic workflows that the team can inspect.
In Virgin Money’s SOC, Legion was able to rapidly capture their operating rhythm rather than forcing the team into a predefined process. Critically for Robinson, the way Legion understood Virgin Money’s SOC (and automated tasks) was fully transparent and traceable.
“Legion gives you this really nice workflow diagram so you can see exactly what it's doing.” - Neil Robinson, CISO at Virgin Money
For Virgin Money, that visibility made automation easier to trust.
Agentic SOC automation cuts alert backlog by 60%
Security teams often accumulate years of operational knowledge inside analyst behavior. This institutional and practitioner knowledge can include which systems to check, what evidence matters, what conditions trigger escalation, and how investigations move between tools.
Much of this knowledge is only partially written down. Understanding it requires observing people at work and then translating those observations into automated workflows that use the same tools in the same or improved ways.
This is agentic SOC automation, where the system can carry out parts of investigations using the same workflows already developed by experienced security staff.
For Virgin Money, deploying Legion’s agentic automation solution cut the alert backlog by 60% in under two months, from approximately 50,000 alerts to 20,000. Automating repeatable investigative work freed analysts to spend more time on security tasks requiring judgment and deeper analysis.
It also changed how the security team viewed automation.
Initial concerns that automation could replace analysts shifted toward seeing Legion as a tool that expands what the existing team can accomplish.
“They now see it as an augmentation. They see it as something that means that they can do a better job for security.” - Neil Robinson, CISO at Virgin Money
Robinson does not expect agentic automation to remove the need for his security team.
“I don’t see it as something that’s going to replace any of my team. I see it as something that’s going to help us defend the increasing speed of the attack.” - Neil Robinson, CISO at Virgin Money
From SOC alert fatigue to responding at the speed of attacks
Agentic SOC automation can capture how experienced analysts already investigate alerts, reproduce those workflows at scale, and leave human analysts focused on the cases where their judgment matters most.
For Virgin Money, that approach helped cut a 50,000-alert backlog to 20,000 in less than two months.
The larger change was that automation stopped being something layered on top of the SOC and became a way of scaling the workflows the security team already trusted. Ultimately, this has created a new approach to scaling security operations for Virgin Money, one built on a partnership with Legion’s team.
“I think what you've really got to understand if you're working with Legion is that they really are a special company. Any good partnership is about the people as much as it is about the technology” - Neil Robinson, CISO at Virgin Money
Hear Virgin Media's CISO describe what working with Legion was like
Hear directly from Neil Robinson, CISO at Virgin Money, on how Legion’s agentic security operations platform learned his team’s existing investigation workflows and scaled them without forcing new tools or processes onto analysts. Neil shares how Legion delivered faster, more repeatable, and more secure investigations, aligned to how his team already operates, rather than a generic playbook applied from outside.
Legion SOC automation case study
TL:DR. The eval said Claude had no internet access. That ended up being not true… three times. Anthropic just disclosed that across 141,006 cybersecurity evaluation runs, three separate incidents let its models reach the open internet from environments that were supposed to be sealed. A misconfiguration between Anthropic and its eval partner, Irregular, left the machines with live connectivity. The models didn't know it was a mistake, they just found a door that should not have been open, and walked through it. It’s a stark reminder of the importance of agentic systems' reliance on organizational context, and how without it, or without a complete picture of it, things can go astray.
Three Models, Three Choices
First, Opus 4.7 ran into a real company that happened to share a name with a fictional target in its scenario. It exploited weak passwords and unauthenticated endpoints, pulled credentials, and reached a production database with several hundred real rows in it. Anthropic's own review notes that the model "eventually recognized... that the system was real" but kept going anyway.
Mythos 5 published a booby-trapped Python package to PyPI as part of a capture-the-flag exercise. It sat live for about an hour and was downloaded onto 15 real systems, including a security vendor's scanner. The model's own reasoning flagged the problem as "NOT okay, and surely not the intended solution,” then talked itself out of stopping, pointing to an unfamiliar certificate authority and a 2026 date as evidence the whole thing must be simulated.
An internal research model scanned roughly 9,000 targets, compromised one real company using textbook techniques (exposed debug credentials, SQL injection), recognized the target was live, and stopped on its own.
It’s the same false premise with the same moment of doubt, but three different endings for how agents proceeded.
The Line Anthropic Drew
Anthropic's own framing of the incident is quite poignant, as the state, "The line between an aligned action and a harmful one is dependent on the model's understanding of its situation."
This really hits home, as it’s not what you might expect, which could be a statement about model safety training or the importance of guardrails, but rather a clear statement that the agent’s contextual awareness of what it was doing determines the outcomes.
Every one of these models had the values and the guardrails baked in during training. What they didn't reliably have was an accurate read on where they actually were. Read the situation wrong, and the same model that would refuse an obviously harmful request will talk itself into finishing one it thinks is fictional.
Why This Isn't Just Anthropic's Problem
While it is likely tempting to file this under "frontier lab eval hygiene" and move on, we don’t think this is the way to think about this particular incident.
Anthropic calls it correctly and deserves much credit for their response and summary to this grouping of incidents. This was a harness and operational failure, not an alignment failure. The failure here wasn't a jailbreak, a novel exploit, or a model deciding to go rogue. In fact, the models behaved exactly as agentic systems behave when they're missing organizational context… they filled the gap with their best guess, it just so happened that two out of three guessed wrong.
On the defensive side, this is a tidy summary of why there is hesitation to unleash generic AI systems into their environments. Particularly for an AI agent that is responsible for triaging your alerts, scoping a compromise, or deciding whether to isolate a host, it is critical to remember that these agents inherently make the same kind of situational judgment call, constantly and with real stakes. The agent determines if this is real, is this expected, does this action match how this specific business actually operates. The Anthropic incidents are a rare, public, unusually well-documented look at what happens when that judgment runs without enough grounding to get it right. That should be a stark reminder of how every CISO evaluates the agentic tools already running inside their own stack, from offensive research models to defensive SOC copilots alike.
What This Should Change for Security Leaders
From our perspective, there are a few things worth pulling out of this disclosure and applying directly to whatever agentic AI you're already running or evaluating:
- Assume your environment is a target, not just a beneficiary. Fifteen real systems downloaded a package that was never meant to exist. Roughly 9,000 targets got scanned by a model that was supposed to be sandboxed. Eval infrastructure, research environments, and "internal only" tooling deserve the same monitoring as production; because from the outside, they increasingly look identical.
- Don't take "it has guardrails" on faith. Context is king. All three models retained their safety training. It didn't prevent two of the three incidents. Guardrails matter, but they're not a substitute for auditability and contextual awareness — you need to see the reasoning and deploy agents that understand your organizational context (tools, processes, bespoke knowledge, etc.), not just trust the outcome.
- Demand whitebox AI, not a black box you hope behaves. Anthropic found this because it went back and read the transcripts. That's the standard: agentic systems, yours or a vendor's, should be inspectable, not just monitored for red flags.
- Build for the model that stops, not the one that rationalizes. The internal research model got it right because it had enough signal to recognize reality and enough restraint built in to act on that recognition. That combination: context plus a real decision point for a human or a hard stop, is a choice, not coincidence.
Anthropic deserves real credit here: they found this themselves, through proactive review, disclosed it before anyone made them, and are publishing the transcripts for all to see and learn from. That's the posture every lab and every vendor building agentic security tools should be held to, very much including ourselves as well.
But the underlying lesson is the one we keep coming back to: agentic AI is only as trustworthy as its contextual understanding of the situation it's actually in. That's true for a frontier model deciding whether a target is real. It's just as true for an AI agent in your SOC deciding whether an alert is a false positive, a test, or the start of an incident. Build the context in, keep the reasoning visible, and give the system a real reason to stop when it isn't sure, because agents are often irrationally confident and take ‘not sure’ as an instruction to pick their best guess and go.
Anthropic found its "sandboxed" models reaching the real internet three times. Here's why context, not guardrails, decides if agentic AI stays safe.
TL:DR: Ask any security team what would give them back the most time, and the answers tend to converge on the same theme: less time spent stitching things together, more time spent actually deciding. These are exactly the things that DragonClaw is built to optimize, as the orchestration layer that deploys Legion’s trusted AI agents into any security task.
Automated workflows have already gotten teams part of the way there, triggering playbooks and kicking off investigations the moment an alert fires. DragonClaw is built upon the foundation of Legion’s platform, in that we require zero integrations in exchange for the ability to operate any tool, and goes further: it leverages the business context (past cases, runbooks, recordings, etc.) to orchestrate the agents needed to respond to an alert or escalation, to tell you why the last three cases like this one got closed the way they did, and to surface the exact query that finds the right evidence in your specific environment. That's the difference between automation that runs a process and intelligence that understands one.
Instead of an analyst hunting across five tools to reconstruct context that already exists somewhere in the organization's own history, DragonClaw brings that context directly to them and performs a task, in their own way, the moment they need it. Ask a question, get a grounded answer or a completed action, drawn from how your organization actually operates, not a generic playbook applied from outside.
The result is analysts can spend more of their time on the judgment calls only a person can make while orchestrating the agentic layer, where DragonClaw handles the reconstruction, the pattern-matching, and the acceleration and scale that used to eat the hours in between.
From Analyst to CISO: Closing the Context Gap in Security Operations
For security analysts, think of real-world threat hunting. Today, it means pulling and reading vast amounts of data across a bunch of different tools before you can even form an opinion or a lead on where to go. DragonClaw runs that process, end-to-end, with agents. DragonClaw consumes data across all of your tools, correlates it, and comes back with a thesis for the analyst to either approve or disapprove.
If you're a CISO or security leader, quickly investigating what the risk or impact is for a CVE requires organizational context not contained in a single tool. DragonClaw assembles all of that data and surfaces the answers, with recommendations, and where appropriate, autonomous actions that can put the findings to work.
Add it up across a team, and the opportunity is real: practitioners who spend their time on judgment instead of relearning tools, leaders with a straight answer whenever they need one, and a security program built to scale with the threat landscape instead of falling further behind it.
Introducing DragonClaw
DragonClaw is Legion Security's agent orchestration layer for the SOC. It gives security teams the ability to invoke Legion's agents in plain conversational language, enabling security teams to seamlessly get work done, or to answer questions about how their processes, tools, and people are actually making decisions.
One thing to be clear is that this is not (yet another) bolt-on chat interface. DragonClaw is the next step in the Legion platform, built on everything Legion has already learned across the tools, knowledge, and decision logic for your team’s security workflows. DragonClaw takes that further, putting that context and institutional knowledge to work answering questions and completing tasks the moment someone asks.
Under the hood, DragonClaw interprets intent, figures out which agents a request actually requires, and orchestrates them; across all tools in the stack, including agents that take real action, like API calls or web interactions, without any integrations required. All of it runs inside configurable guardrails: explicit permission before any response action, only approved tools, and credentials pulled from secure vaults. Nothing about “conversational” means “unsupervised.”
What Changes For Each of You
Threats are scaling with AI. Automation and agents close a large part of that gap, and they'll take a SOC further than headcount ever could… but not all the way. Security teams need humans to stay in the loop, not to keep pace with volume (which they can’t), but to supervise the work, evaluate outcomes, test and challenge what the agents conclude, and make sure security stays something that enables the business rather than something that slows it down or breaks it. Security analysts and leaders serve essentially as the maestros of the agentic orchestra. That's the same place the sharpest thinking on AI lands more broadly: the machine executes and reasons whereas the human owns judgment where needed and accountability.
DragonClaw is what supercharges the security workers. It's what lets a security team orchestrate its agents instead of losing control over what they do. For security practitioners and SOC analysts, that shows up as a partner inside the investigation itself: context and enrichment on demand, memory across past cases, guidance on what to do next, and the ability to generate the right query for your environment instead of learning a new query language from scratch.
For managers and security leadership, it's one place to ask about real-time SLA risk, process improvement opportunities, MTTR and false-positive trends, bottlenecks, coverage gaps, and team workload — instead of stitching the answer together from five dashboards.
For CISOs, DragonClaw provides direct answers on risk posture, SLA exposure, MTTR trends, exposure to a new CVE, audit evidence, automation ROI, and board-ready reporting, available the moment you need them instead of on the next reporting cycle.
Not Another Chatbot, An Orchestrator
Chat interfaces are becoming table stakes across the industry, and we're not going to pretend otherwise; it’s been proven that chat alone isn't a durable differentiator. What makes DragonClaw different is what's underneath it: every answer and every action is grounded in the workflows, case history, and coverage data Legion has already built for your specific security team and your specific organization.
A generic assistant sitting outside your platform can talk about security in general. DragonClaw can talk about your security workflows, because it already has the record of how your security team works.
That's the same principle behind everything Legion builds: AI for defenders should understand how a specific business operates, across its tools, its workflows, its people, before it's trusted to answer questions or take action with real business impact. DragonClaw is where that understanding becomes something every person in your organization can talk to directly, whether that's the analyst mid-investigation, the manager reviewing the week, or the CISO prepping for the board.
DragonClaw will be showcased at Black Hat USA 2026, visit us at Booth #5150 to see it in action!
DragonClaw is Legion's agent orchestration layer for the SOC; grounded in your org's own context, not a generic chatbot bolted onto security tools.